
We are a community of systems software engineers who focus on the internals of database management systems, data systems, and data-intensive applications
Our members engineer data systems at:
What We Do
Learn how databases really work by reading, building, and measuring them together.
Bi-Weekly Deep Dives
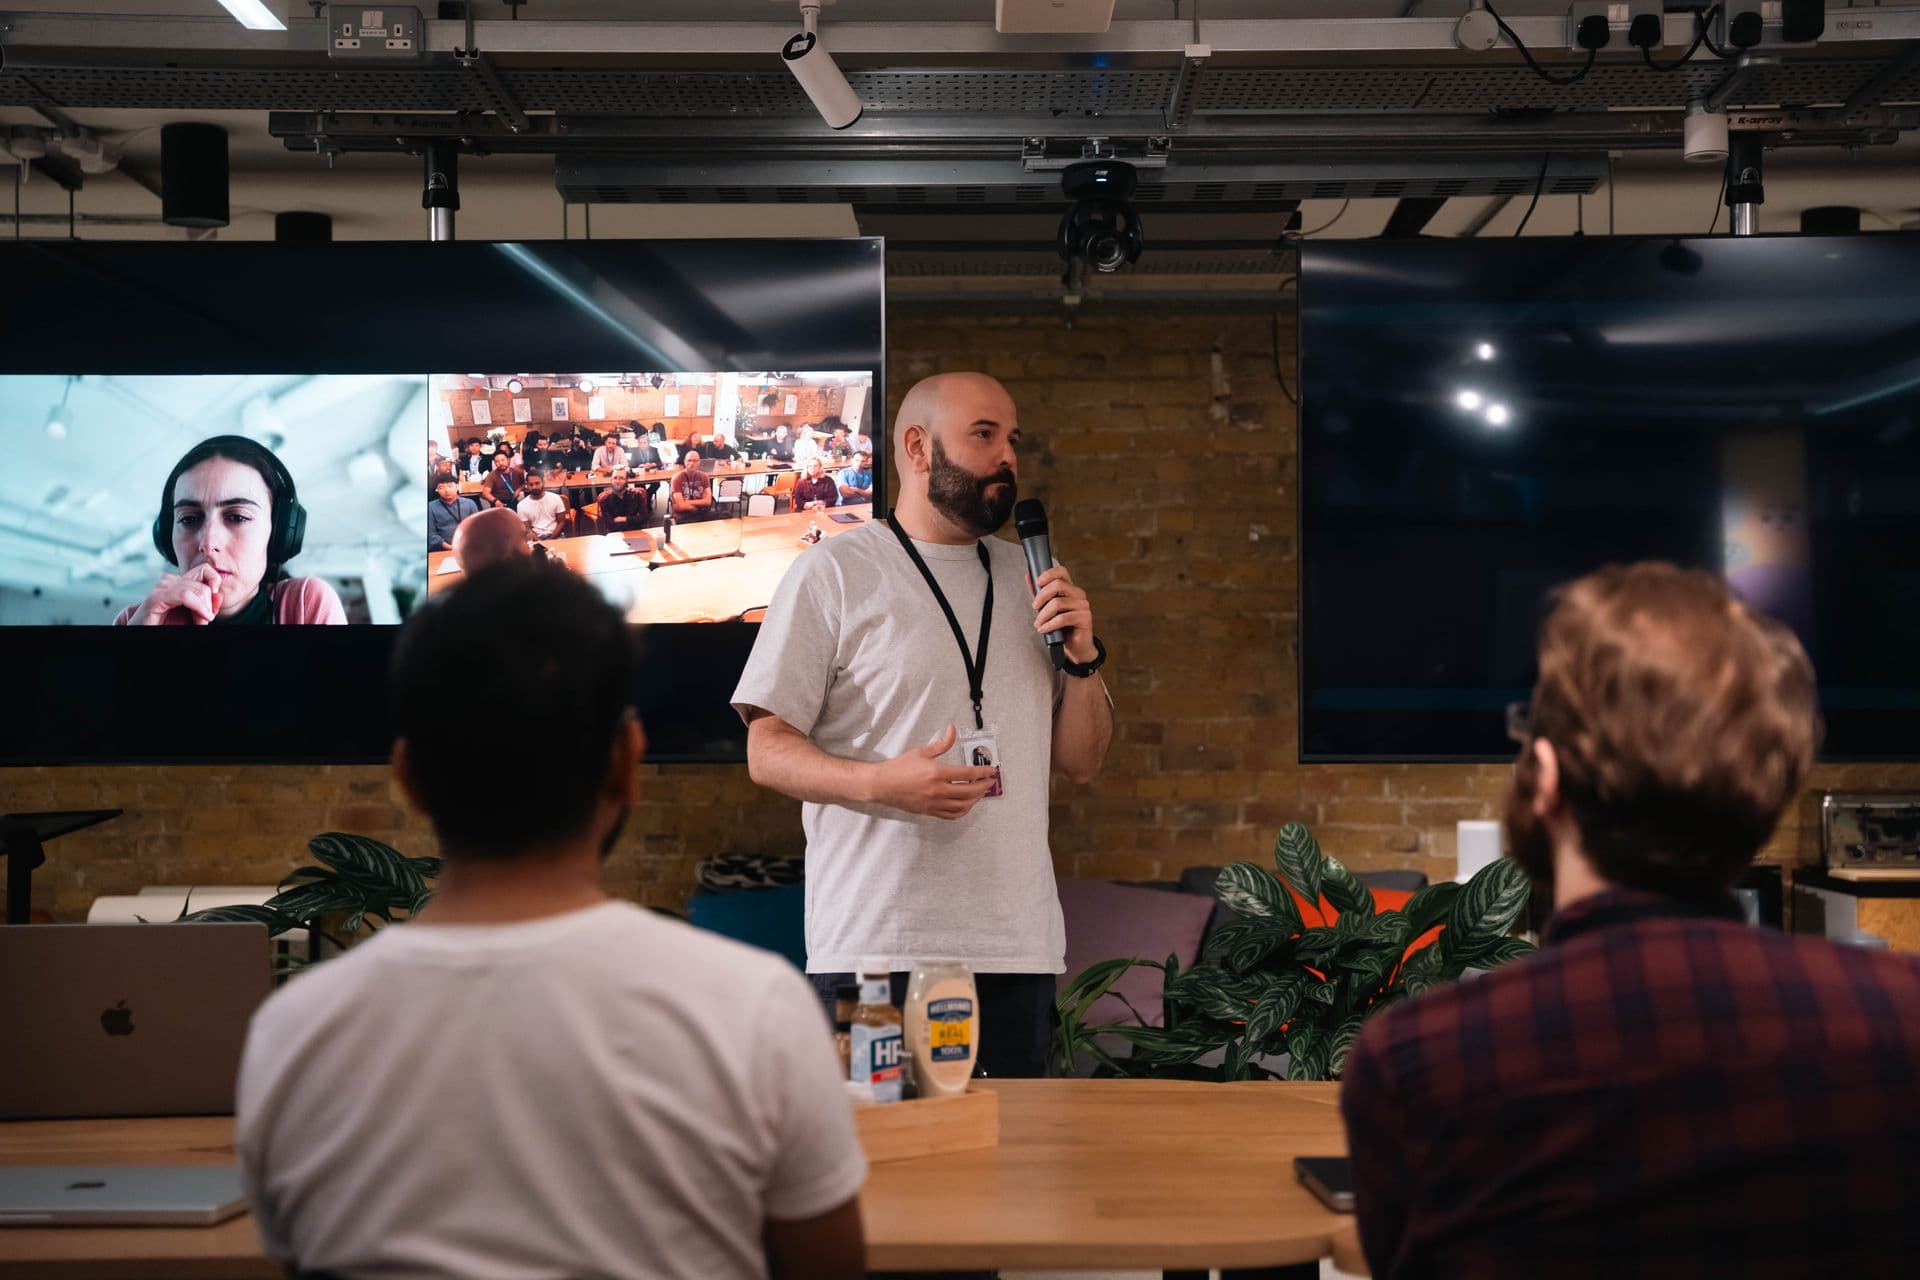
01Every other week we take a database apart together. Classic and cutting-edge papers, walkthroughs of real codebases, and live design sessions on storage engines, indexing, and query execution.
A Home for Database Engineers
02Students, researchers, and working engineers learning side by side. Ask the questions you think are too basic, get your code reviewed, and find mentors who have walked the path before you.
Research on I/O & Storage
03We measure how storage really behaves, then share what we find. Completion vs. readiness I/O models, page caches, and the low-level mechanics that decide how fast a database can go.
We care about the internals of databasesystems and the I/O subsystem

Query Parser & Optimizer:
Parsing SQL/queries, Abstract Syntax Trees (AST), and cost-based query optimization.

Execution Engine:
Volcano iterator execution, batch vectorization, and physical plan processing.

Buffer Pool:
Page frame allocation, memory management, and cache eviction policies.

Storage Engine:
B+ Trees, LSM-Trees, page layouts, Write-Ahead Logging (WAL), and transaction management.

Disk:
Persistent storage layout, block devices, and physical write constraints.
I/O Models :
Kernel-based (e.g., epoll, io_uring) and user-space I/O models.
The fundamental architecture
of our existence
We are relentlessly inquisitive about what happens beneath the abstractions—from hardware physics and OS kernels to database query planners.
We go past surface-level explanations; we read the paper, reimplement the storage engine, and understand the internals rather than just talking about them.
Engineering data systems requires precision. We analyze edge cases, write benchmarks, evaluate tradeoffs, and verify correctness at every layer of the stack.
We share knowledge openly, mentor aspiring systems engineers, open-source our research implementations, and cultivate a community of continuous growth.
Your Questions.
Answered.
Contact us if you have any other questions.
Click the link in the header and fill out the form. Our team will reach out after your profile is reviewed.
Both students and working professionals are welcome. Anyone who is passionate about systems programming, databases, and low-level software architecture is encouraged to participate.
No prior DBMS development experience is required. A foundational curiosity in software engineering and computer systems is all you need to get started.
We hold interactive bi-weekly sessions covering paper readings, live systems architecture walkthroughs, open-source codebase reviews, and guest lectures.
Yes! Members are encouraged to present their open-source contributions, research experiments, or technical deep-dives to the community.
Yes, experienced systems engineers and academic advisors actively provide mentorship, code reviews, and structured study paths for newcomers.
Yes, our community is globally open. All sessions and paper discussions are hosted online with hybrid participation.
Companies can sponsor technical meetups, cloud infrastructure for research projects, or propose collaborative engineering challenges. Reach out via the contact form.
Join our mailing list and follow our announcements on our community channels to get notifications for all upcoming sessions and hackathons.